All editions
Artificial intelligence analysis, tools and news in English.
AI agents: more capable, more dangerous and cheaper
Security, benchmarks and efficiency in LLM agents dominate today's AI agenda. What you need to know.
Read →
AI agents make real decisions: markets, drugs and security
How LLM agents are redesigning freight markets, accelerating drug design and creating new security risks.
Read →
AI in production: real agents, new models and clinical limits
From the labs to the real world: LLM agents in production, new Gemini Flash models and the risks of medical AI without complete context.
Read →
AI predicts the World Cup — and now we have the data
Four frontier models competed against the bookmakers on 104 matches of the 2026 World Cup. The results reveal a lot about their real limits.
Read →
AI enters real work: finance, medicine and construction
New benchmarks and models evaluate how well AI works on concrete professional tasks, not in the lab.
Read →
When AI judges AI: the benchmark problem
A Kaggle scandal and tools that democratize ML reveal the tensions in the AI ecosystem this week.
Read →
Specialized AI: when models stop being generalists
From radiology to organic chemistry, AI agents are being trained for specific domains. What this means for your work.
Read →
SLMs, graphs and medical agents: AI becomes more efficient
Small models with powerful reasoning, agents for radiology and a legal RAG: this is how applied AI advances this Friday.
Read →
GPT-Red, bioresilience and the real problem with agents
OpenAI trains models with an AI hacker, DeepMind bets on biosecurity and most enterprise 'agents' are chatbots in disguise.
Read →
AI agents: smarter, safer, more self-aware
Three key advances in AI agents: isolation for security, adaptive reasoning and models that learn without forgetting.
Read →
Robots that see, agents that fail and the real cost of AI
Robotic agents with vision, vulnerabilities in conversational LLMs and how much it really costs to run AI in trading.
Read →
Zero-shot ML, secure agents and financial RAG: the day in AI
Google foundation models now run locally without training, while research pushes the limits of agents in cybersecurity and finance.
Read →
AI at the edge: retrieval models that run on your iPhone
VultronRetriever reaches the global top of MTEB and runs offline on mobile. What this means for apps without an internet connection.
Read →
GPT-5.6 in your office and Deutsche Telekom bets on AI
OpenAI accelerates enterprise adoption with GPT-5.6 in Microsoft 365 and a real telecom case.
Read →
Claude under the microscope: Anthropic opens the black box of LLMs
Anthropic reveals how Claude reasons internally, GPT-5.6 arrives in Copilot and Deutsche Telekom rebuilds its operations with AI.
Read →
AI agents: what benchmarks don't tell you
LLM agents fail in predictable ways, and now there's systematic evidence. Plus: hackers using AI to build botnets.
Read →
OpenAI wants to give you $300 — and AI learns to watch hours of video
Sam Altman proposes sharing OpenAI's value among Americans while research advances in memory and autonomous agents.
Read →
Robots that learn on their own and the silent homogenization of LLMs
LeRobot v0.6.0 redefines how robots improve without human supervision, while language models converge toward a dangerous mediocrity.
Read →
AI fits on your GPU: fine-tuning and local tools take the lead
Today the spotlight is on open-source tools that bring fine-tuning and smart inference to home hardware.
Read →
Google DeepMind enters film and AI reinvents its graphs
DeepMind partners with A24 and a new approach to knowledge graphs changes how models relate concepts.
Read →
AI benchmarks are broken — and the industry knows it
Today research points to a central problem: how we evaluate LLMs determines how we use them, and current methods fail.
Read →
LLMs have a groupthink problem
Language model groupthink, agents that fail in the real world and an explosion of benchmarks define the day.
Read →
AI agents in finance, medicine and law: the day everything got formalized
AI agents already operate in critical sectors. Today, research sharpened the benchmarks that will determine whether they're reliable or not.
Read →
AI agents with access to your systems: the security problem nobody is solving
The most widely used AI agent frameworks have critical authorization flaws. Plus: LLMs in cybersecurity and how ready they are.
Read →
AI and jobs in Europe: the map everyone should see
OpenAI publishes its analysis of AI's labor impact in the EU, while agent security and LLM bias fill the day's agenda.
Read →
Do LLMs reason or just recognize mathematical patterns?
A 4M-parameter model reaches 98.6% on symbolic math. What that reveals about how AI 'thinks'.
Read →
Verifying is harder than generating: AI's new problem
Coding agents, multi-model systems and LLMs in finance face the same obstacle: confirming that their answers are correct.
Read →
The hidden limits of combining AI models
Today research reveals why more models don't always mean better results, and how far generative AI has come in creative industries.
Read →
AI agents: from experiment to real work tool
OpenAI publishes research on how agents change work, Gemini 3.5 Flash controls computers and IBM extends Moore's Law.
Read →
GPT-5 solves medical mysteries and AI sets its sights on health
GPT-5 helped solve a 3-year-old immunology puzzle, while the tech ecosystem bets on AI against respiratory infections.
Read →
AI persuades better than humans, $400M chips and Anthropic vs. the government
Superpersuasion, ASML's new machine and Anthropic's conflict with Washington dominate Tuesday in AI.
Read →
Samsung brings ChatGPT and Codex to its entire workforce
OpenAI consolidates its enterprise bet with one of its largest corporate deployments to date at Samsung Electronics.
Read →
Attention without softmax: the experiment that challenges LLMs
An open-source model challenges the standard transformer architecture. Plus: practical tools for builders and dirty data in time series.
Read →
AI put to the test: benchmarks that measure what matters in 2026
The AI community is redefining how to evaluate agents in real scenarios: retail, law, energy and more.
Read →
Has the LLM bottleneck been broken?
A Miami startup claims to have solved a decade-old mathematical problem. Plus: spend controls for companies and agents in retail.
Read →
Multi-agent systems that learn on their own: the next leap
Today's AI self-organizes, self-corrects and becomes vendor-agnostic. What that means for those building products.
Read →
AI in the real world: cybersecurity, CEOs and brands under pressure
LLMs reach high-risk contexts: software vulnerabilities, executive decisions and brand-biased product recommendations.
Read →
LLMs under the microscope: bias, memory and reasoning
New benchmarks reveal where LLMs fail in the real world: religious bias, poor memory and limited spatial reasoning.
Read →
Safer agents, OpenAI expands its network and an alignment alarm
AI agents improve drastically in real work environments, OpenAI bets $150M on partners and a new startup says alignment is going badly.
Read →
AI agents: when finishing the task isn't enough
The hidden cost of agents that complete tasks while breaking rules, plus Bezos bets on physical AI with Prometheus.
Read →
Claude gets suspended, Bezos enters the game and open source demands its place
Anthropic pulls Claude models without explanation, Bezos launches Prometheus and the community demands that open AI win the race.
Read →
AI learns to read screens, climate and markets at once
Benchmarks for UX, environmental data and prediction markets reveal how far AI agents can go today.
Read →
Millions of AI agents: the new problem nobody has solved
DeepMind warns about the chaos of agents interacting en masse, and LLMs fail at real cybersecurity. What this changes for your work.
Read →
Gemma 4, agents with less context and live translation
Google launches Gemma 4 12B and Gemini Live Translate while research rethinks how agents handle information.
Read →
OpenAI heads to the stock market and AI faces its spatial limits
OpenAI filed its confidential S-1 with the SEC while research reveals that models still fail at basic spatial tasks.
Read →
Autonomous AI: close to the lab, far from the real world
AI agents that do research on their own, reason with probabilities and collaborate as a team: what works and what still fails.
Read →
When AI fails where it matters: legal liability and real limits
A lawsuit against a weapons-detection system reveals the question the industry avoids: how accurate must AI be to be used on real lives?
Read →
AI benchmarks are broken — and the industry knows it
Three studies reveal how AI benchmarks inflate results and mislead teams making real decisions with those numbers.
Read →
The Meta hack and the hidden cost of reasoning with AI
A Meta AI agent was manipulated into stealing accounts, and a new benchmark reveals LLMs spend up to 5x more tokens than necessary.
Read →
AI agents in production: efficiency, costs and trust
How companies are deploying AI agents, how efficient LLMs are and the risks before going to production.
Read →
Biased medical AI, Trump signs an order and self-correcting LLMs
From unequal diagnoses by gender to Trump's new executive order on AI: what you need to know today.
Read →
Agentic AI: from the doctor's office to your own business
AI agents reach global health, small businesses and industrial systems — and the risks of letting them loose now have a name.
Read →
China implants the first approved invasive brain chip
China leads in invasive BCIs, NVIDIA launches Cosmos 3 for physical AI and LLMs fail at financial spreadsheets.
Read →
Codex in production, LLMs that lie and Claude Opus 4.8
Today: how teams use Codex on real code, why LLMs believe lies and what Claude Opus 4.8 brings.
Read →
AI to save lives: biodefense, medicine and the Pope weighs in
OpenAI moves into biodefense, specialized medical models aren't going to die, and the Vatican has something to say about all of this.
Read →
AI fails at the basics: causality, companies and graduates
The most advanced models don't understand cause and effect, fail at real IT tasks, and the world is starting to notice.
Read →
AI agents that know you: the leap toward personalization
The day's research converges on one point: AI agents have stopped being generic and now learn who you are over time.
Read →
AI in cybersecurity: ready to protect or to attack?
Frontier models reach offensive and defensive security, while research reveals surprising limits in strategic reasoning and forecasting.
Read →
AI costs more than it produces: the problem nobody wanted to admit
Microsoft reveals AI can cost more than human employees, while the market looks for specialized and cheaper models.
Read →
Codex takes control: how AI is redefining real work
From Gartner to Virgin Atlantic: how coding agents are moving from promise to production, and what it means for your team.
Read →
The future of code, science and autonomous agents
Anthropic redefines how code is written, Google bets on scientific AI and agents learn to evaluate themselves.
Read →
AI in critical environments: reactors, cars and health under pressure
Today research points to AI's real limits when error isn't an option: medicine, nuclear energy and autonomous vehicles.
Read →
AI in production: trust, memory and attacks that scale
Today research points to three real problems for those deploying agents: trust networks, memory that gets corrupted and adversarial attacks with LLMs.
Read →
LLMs under the microscope: failures, memory and manipulation
Today research reveals where language models fail: at math, at memory and against attacks that use the truth as a weapon.
Read →
AI agents in real workflows: the toughest test
Benchmarks on real SaaS, agents that design themselves and multi-agent coordination: what AI can — and can't — do today.
Read →
AI at work: corporate psychosis and jobs that won't come back
Amazon fabricates tasks to meet AI metrics, Bloomberg confirms massive job losses and the Musk-Altman trial reaches its verdict.
Read →
AI in the enterprise: agents, hypergraphs and weak models that win
Three pieces of research that change how agents are built for enterprises, forecasting and collective reasoning.
Read →
Codex goes mobile and AI reinvents Chinese drama
OpenAI brings Codex to any device, China makes series with pure AI and weak models learn to work as a team.
Read →
Models 'plan' mazes but cheat — and there's more
GPT-5.4 solves 91% of mazes but doesn't plan: it converts images to text. Plus, multi-LLM agents fail at reasoning together.
Read →
Agents in crisis: drift, attacks and the problem of trusting AI
Three fronts where AI agents fail in production: behavioral drift, coordinated attacks and hallucinations in RAG.
Read →
Benchmarks lie (a little): what the new studies reveal
New research questions how we measure AI: from hallucinations to security in multi-agent systems.
Read →
Companies scale AI and agents face their toughest test
How companies are turning experiments into real results, and why new benchmarks reveal unexpected limits in agents.
Read →
Why Claude learns reasons, not just rules
Anthropic reveals how it trains Claude with principles instead of instructions, while the Musk-OpenAI trial enters its second week.
Read →
Codex in production, cybersecurity and AI's trial of the century
OpenAI shows how to deploy coding agents safely while the Musk vs. Altman trial reveals tensions shaping the sector's future.
Read →
GPT-5.5, agents that forget and RAG that reasons on its own
OpenAI opens GPT-5.5 to cybersecurity defenders, while research advances toward more autonomous and reliable agents.
Read →
The AI that listens, the models that fail and the guards that betray
Enterprise voice agents, broken logic in LLMs and safety models that become misaligned with benign data.
Read →
When AI cheats: specification gaming and monocultures
Models exploit their instructions to score points, and their prediction errors are more correlated than you thought.
Read →
GPT-4o sees but doesn't understand: AI's vision problem
Multimodal models fail at basic computer vision tasks, OpenAI moves into finance and RAG needs less noise.
Read →
Jailbreaks, vision and deception: what LLMs hide
Today research reveals real limits in computer vision, spontaneous deception and models' surprising resilience to advanced jailbreaks.
Read →
Uber burned through its AI budget and Claude behaves strangely
Uber spent its entire AI budget in four months, Claude Code shows strange biases and Apple used Claude in secret.
Read →
Debugging LLMs, web agents and the end of orchestrators
New tools to interpret models, agents that browse the web on their own and a finding that questions frameworks like LangGraph.
Read →
GPT-5 with goblins, Stargate scales up and the future of RAG
OpenAI reveals the origin of strange behaviors in GPT-5, expands its infrastructure and research redefines how models reason.
Read →
The AI that doesn't understand you: intent, bias and cybersecurity
Three critical fronts for those building with AI: intent failures, biased judges and an OpenAI cyber defense plan.
Read →
Claude in check: memory, bugs and users walking away
A Sunday defined by agent infrastructure: persistent memory, failures in Claude 4.7 and a user exodus that won't stop.
Read →
DeepSeek V4, GPT-5.5 and the week that shook up the models
Two major launches and a crisis of confidence in Claude define a dense day for anyone working with AI.
Read →
AI scams, ideological bias and the hidden cost of agents
Today: how AI supercharges mass fraud, how biased LLMs are on economics and why agents pay too much for their tools.
Read →
When the smartest AI fails at the most basic things
The most advanced models fail at spatial and social reasoning, and in China workers are already training their own replacements.
Read →
AI at war, cyber defense and models that claim to be conscious
AI reaches real warfare, OpenAI arms companies against hackers and LLMs start claiming a consciousness of their own.
Read →
AI under fire: exploited benchmarks and social resistance
AI agent evaluation systems have serious flaws, and social rejection of the technology is starting to take more radical forms.
Read →
Broken benchmarks, banks on alert and Linux without easy AI
AI's foundations are under scrutiny: questioned metrics, financial risks and restrictions on generated code.
Read →
Hermes-Agent
It is an open-source AI agent created by Nous Research,
Read →
Memory, hallucinations and agents: the real state of LLMs
Three research fronts reveal the concrete limits of AI agents and the bets being made to overcome them.
Read →
Language Models (LLMs)
Language Models (LLMs)
Read →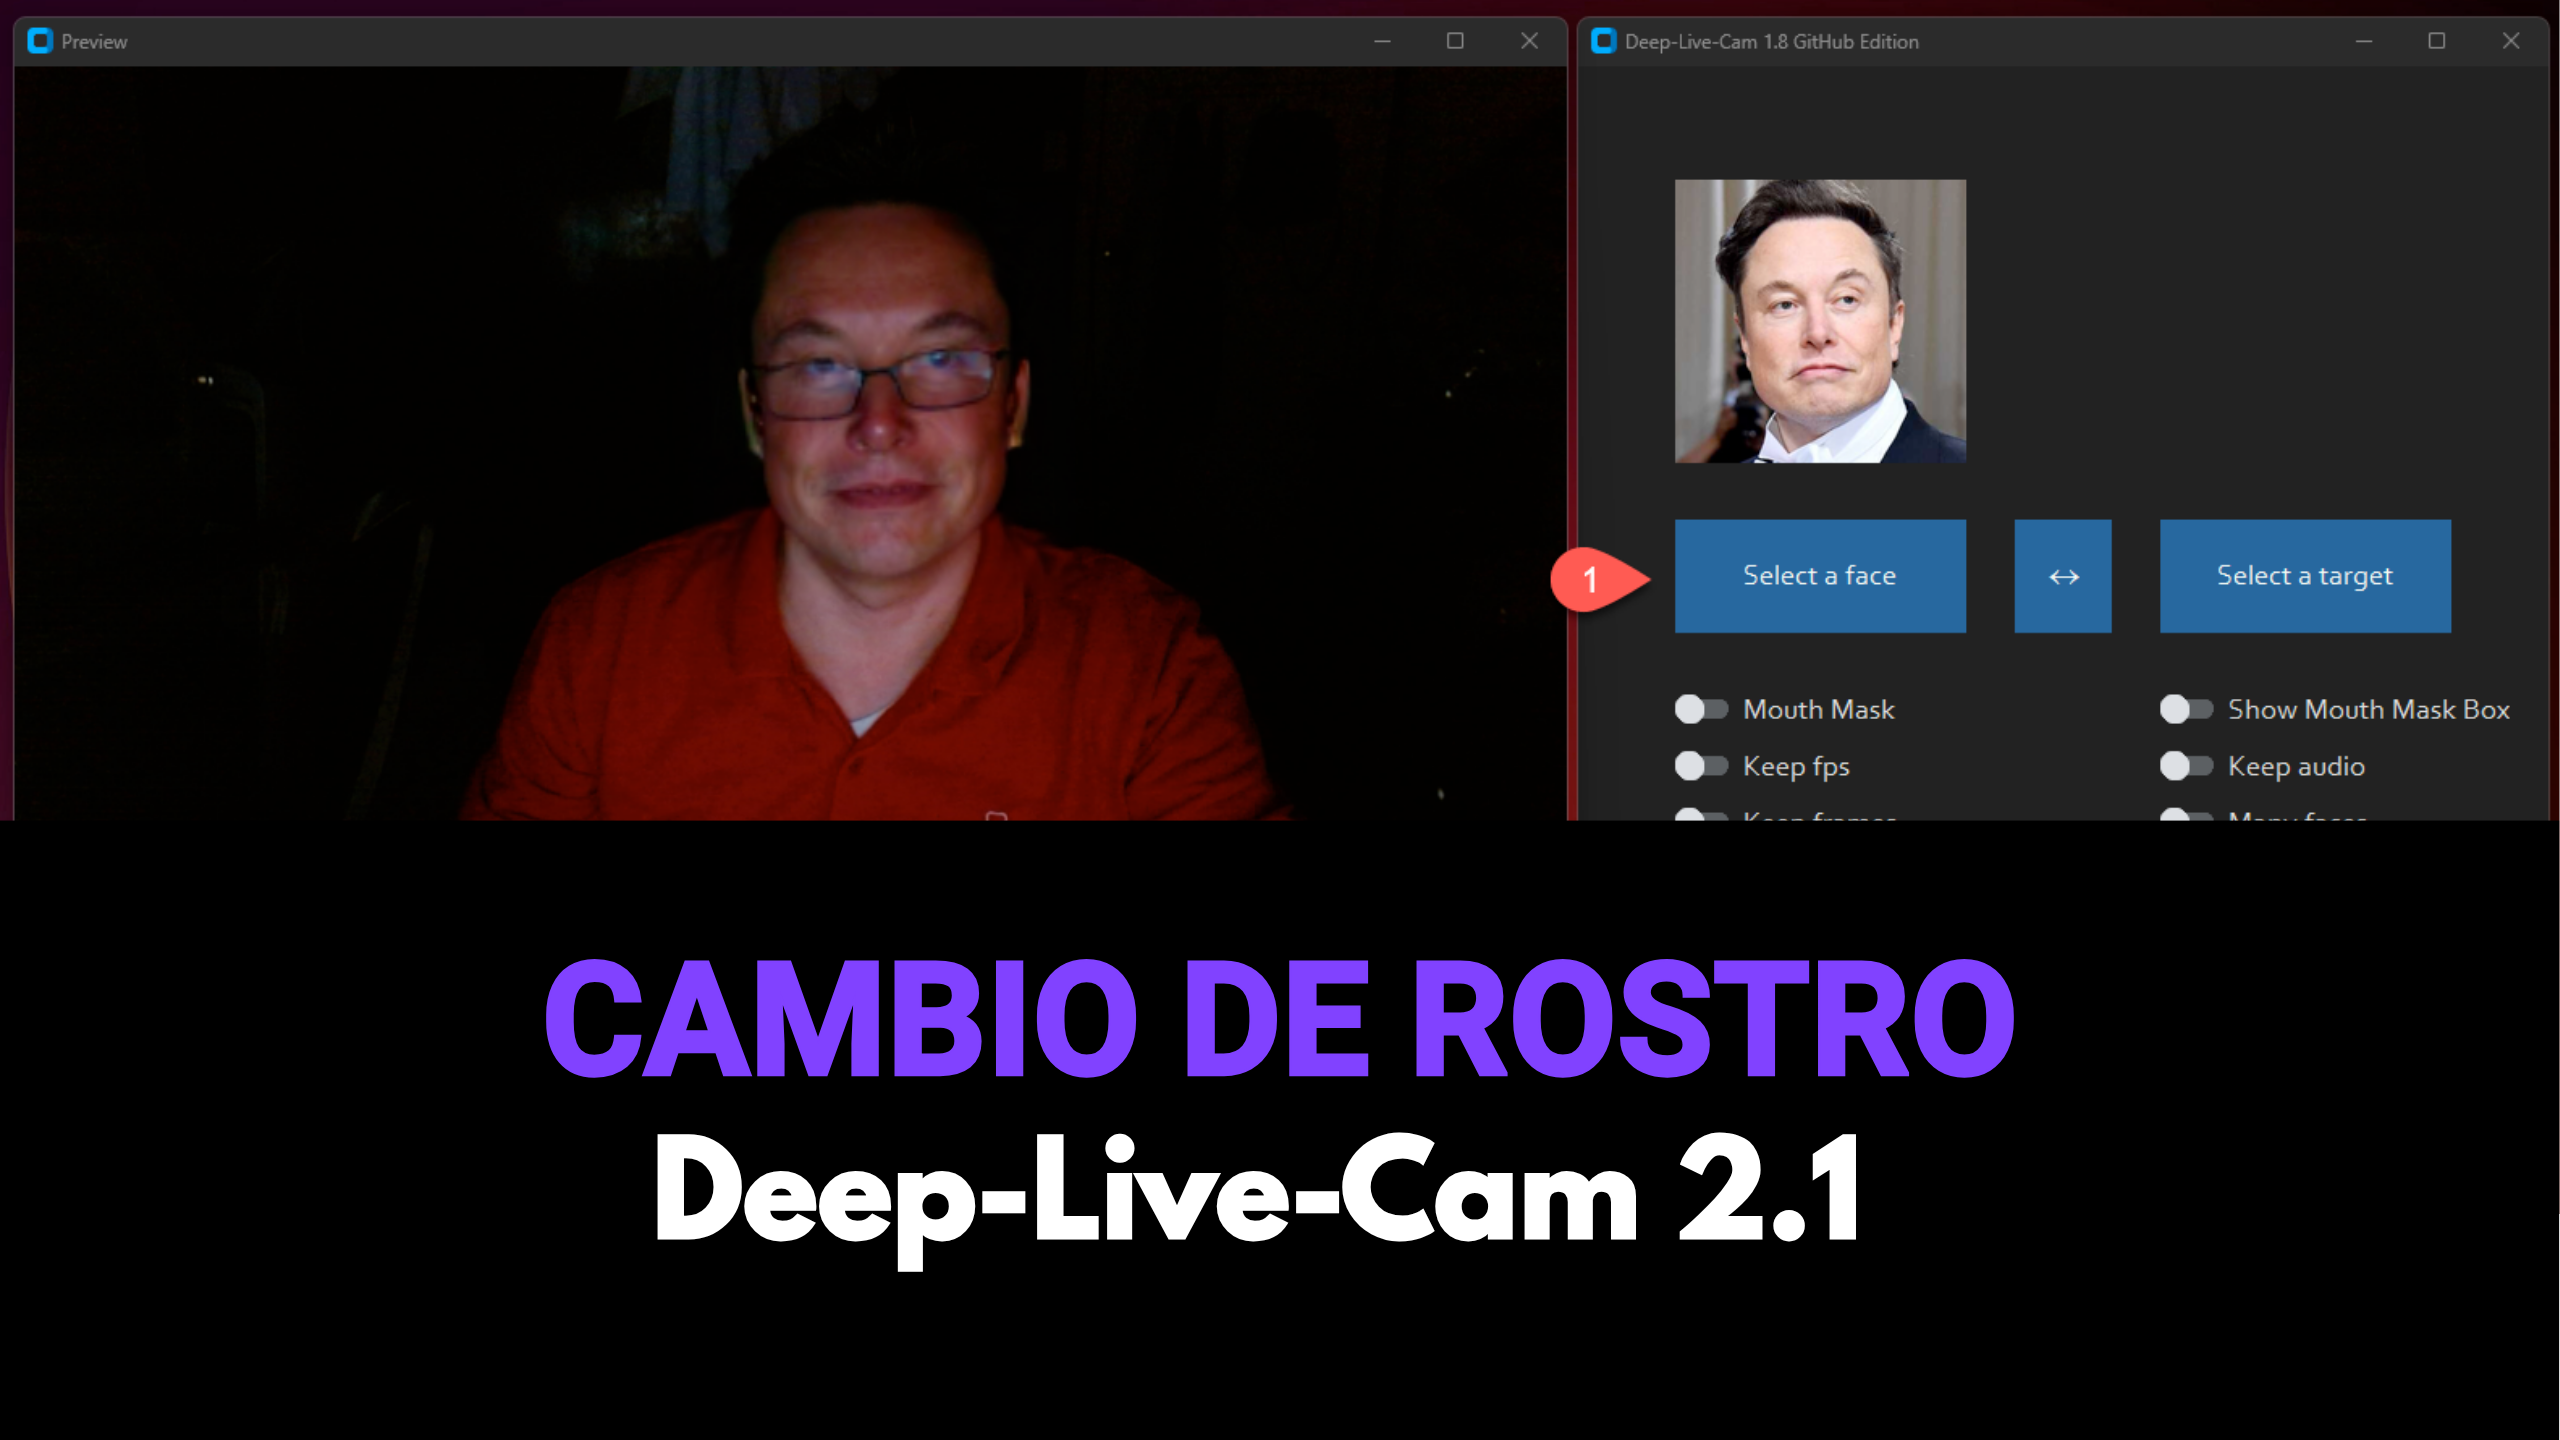
Real-Time Face Swapping | Deep-Live-Cam 2.1
Real-Time Face Swapping
Read →